Check out Part 2!
Part 2 has the latest instructions on installing llama.cpp using yum: How to Run LLMs on IBM i Pt. 2
Note: This is experimental work.
This guide is a work in process and is intended for experimentation and prototyping.
Expect rough edges, manual steps, and a few patches along the way.
Happy building!
In this post, I’ll walk you through how I successfully built llama.cpp on IBM i, step-by-step—from configuring the environment and compiling the source to running a local LLM right on the system. You’ll also learn how to prep a compatible model and test it using the built-in CLI, HTTP server, and web UI.
What is Llama.cpp?
llama.cpp is a lightweight, blazing-fast C++ implementation for running Large Language Models (LLMs) locally on a wide range of hardware—no internet, no cloud, no external dependencies. It’s the engine powering many popular tools like Ollama, LM Studio, and other open-source AI apps. And now—for the first time—you can run it directly on IBM i
Why run LLMs locally on IBM i?
If you’ve been curious about integrating LLMs into your applications, this is the perfect way to get started. Running LLMs directly on IBM i enables quick, cost-free prototyping of AI-powered features, all within your existing environment:
- Build a chat-style interface for interacting with system data
- Experiment with text generation, summarization, or code suggestions
- Package and test ideas locally—no need to send data off the box
Build Llama.cpp on IBM i
First make sure you have the open source environment installed on your IBM i system. you can follow directions here: RPM pile for IBM i releases in standard support — IBM i OSS Docs documentation
to configure your environment.
1. Install Open source packages
Install the required open source packages:
- gcc12
- gcc12-cplusplus
- libutil2
- git
- cmake
- openblas
- openblas-devel
- libpthread-stubs-devel
- binutils-gnu
- libutil-devel
Optional (but recommended):
- ccache
# Required packages
yum install gcc12 gcc12-cplusplus libutil2 git cmake openblas openblas-devel \
            libpthread-stubs-devel binutils-gnu libutil-devel

# Optional (but recommended)
yum install ccache
Note
On some P10 systems, you may need to explicitly use binutils-gnu :
cd $HOME
mkdir bin
ln -s /QOpenSys/pkgs/bin/gnu-as bin/as
export PATH=$PWD/bin:$PATH
2. Clone Llama.cpp Repo
Clone the llama.cpp repo on IBM i
git clone https://github.com/ggerganov/llama.cpp
cd llama.cpp
Checkout tag release
git checkout -b ibmi tags/b5043 this is the latest tag I used. Cloning the most recent release will likely work just fine.
3. Make a small patch
Once you have the llama.cpp repo cloned, we need to make a small change to the source code so that it will work on IBM i. go to llama.cpp/src/llama-mmap.cpp and comment out the RLIMIT_MEMLOCK logic found on around line 484-490:
llama.cpp/src/llama-mmap.cpp at e391d3e · ggml-org/llama.cpp
# Open this file in your preferred text editor:
vim src/llama-mmap.cpp
Here is the exact code:
struct rlimit lock_limit;
if (suggest && getrlimit(RLIMIT_MEMLOCK, &lock_limit)) {
    suggest = false;
}
if (suggest && (lock_limit.rlim_max > lock_limit.rlim_cur + size)) {
    suggest = false;
}
4. Build
Now we are ready to run the build. Navigate to the root of the llama.cpp repo and run the following:
cmake -B build_cpu \
  -DCMAKE_AR="/QOpenSys/pkgs/bin/gcc-ar-12" \
  -DCMAKE_RANLIB="/QOpenSys/usr/bin/ranlib" \
  -DCMAKE_C_COMPILER=/QOpenSys/pkgs/bin/gcc-12 \
  -DCMAKE_CXX_COMPILER=/QOpenSys/pkgs/bin/g++-12 \
  -DCMAKE_CXX_FLAGS="-pthread" \
  -DCMAKE_EXE_LINKER_FLAGS="-pthread -lutil" \
  -DCMAKE_CXX_ARCHIVE_CREATE="<CMAKE_AR> -X64 qc <TARGET> <LINK_FLAGS> <OBJECTS>" \
  -DCMAKE_CXX_ARCHIVE_APPEND="<CMAKE_AR> -X64 q  <TARGET> <LINK_FLAGS> <OBJECTS>" \
  -DCMAKE_CXX_ARCHIVE_FINISH="<CMAKE_RANLIB> <TARGET>" \
  -DCMAKE_BUILD_TYPE=Release
Current Build Summary
- native CPU build for either Power 9 or Power 10
- Threading and OpenMP enabled
- Release build type
Run build
cmake --build build_cpu --config ReleaseNote
If you encounter errors with sgemm.cpp :
error: static assertion failed: RN/RM values not supported
static_assert(false, "RN/RM values not supported");
You’re likely hitting an issue with the TinyBLAS backend used by llamafile.
This error occurs on some PowerPC architectures due to unsupported instruction patterns in sgemm.cpp, a minimal, highly optimized matrix multiplication routine introduced in #6414 and originally written by Justine Tunney.
How to fix it
Disable the GGML_LLAMAFILE flag during your cmake step:
cmake -B build_cpu \
	... \
	-DGGML_LLAMAFILE=OFF
If you encounter errors with the assembler:
Assembler:
line 1: Invalid -m flag assembly mode operand: PWR10
Valid values are:COM PWR PWR2 PPC 601 603 604 PPC64 620 A35 PWR4 PWR5 PWR5X 970 PPC970 PWR6 PWR6E PWR7 PWR8 PWR9 ANY
Ensure you’re using GNU binutils and not the default system assembler. See the note above on symlinking as. See Note
Verify Build
./build_cpu/bin/llama-cli --helpPrepare a model for Llama.cpp
Next, we need to obtain a model compatible with Llama.cpp and transfer it to the IBM i system. Since IBM i does not support some of the required Python dependencies, we’ll first download the model locally and then manually transfer it to the system.
Clone the repo on your local machine to get started:
git clone https://github.com/ajshedivy/models-for-i.git
cd models-for-i
The instructions can be found in the README of the repo: GitHub - ajshedivy/models-for-i
Once you are done, you should have an IBM i compatible model (Llama-3.2-1B-Instruct) transferred to your system.
Run Llama.cpp on IBM i
We are almost there! So far, you have:
- built Llama.cpp from source on IBM i
- Downloaded a model from Hugging Face
- Transferred the model to IBM i
Now we are ready to run the model!
Llama.cpp CLI
cd $HOME
./llama.cpp/build_cpu/bin/llama-cli \
	-m ~/models/Llama-3.2-1B-Instruct-f32-be.gguf \
	-p "Hello there!"
Arguments:
-mis the model which we transferred to IBM i-pis the prompt text
Here is a sample output of the command:
== Running in interactive mode. ==
 - Press Ctrl+C to interject at any time.
 - Press Return to return control to the AI.
 - To return control without starting a new line, end your input with '/'.
 - If you want to submit another line, end your input with '\'.
 - Not using system message. To change it, set a different value via -sys PROMPT

system

Cutting Knowledge Date: December 2023
Today Date: 07 Apr 2025

user

Hello there!assistant

Hello! It's nice to meet you. Is there something I can help you with or would you like to chat?

>
There are a ton of options for the main llama-cli:
Check them out and experiment with different combinations. I plan to write a separate blog on performance metrics and more in depth demos
Llama Run (llama-run)
This example is meant to demonstrate a minimal interactive chat:
cd $HOME
./llama.cpp/build_cpu/bin/llama-run ~/models/Llama-3.2-1B-Instruct-f32-be.gguf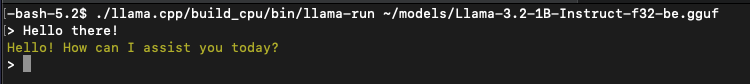
llama-run docs:
Llama Server
Llama.cpp comes with a built in fast, lightweight, pure C/C++ HTTP server and a set of LLM REST APIs and a simple web front end to interact with llama.cpp
Features:
- LLM inference of F16 and quantized models on GPU and CPU
- Parallel decoding with multi-user support
- Continuous batching
- Multimodal (wip)
- Monitoring endpoints
- Schema-constrained JSON response format
Start the server
cd $HOME
./llama.cpp/build_cpu/bin/llama-server \
	-m ~/models/Llama-3.2-1B-Instruct-f32-be.gguf
This will start the server on port 8080
main: server is listening on http://127.0.0.1:8080 - starting the main loopTest the server
In another terminal, ssh to the same system and run the following command:
curl --request POST \
     --url http://localhost:8080/completion \
     --header "Content-Type: application/json" \
     --data '{
         "prompt": "once upon a time, ",
         "stream": true,
         "n_predict": 50
     }'
Llama.cpp UI
Starting the server will also create a Web UI on port 8080. In a browser, navigate to:
http://HOST:8080
This is still under active development, more info can be found here:
Closing thoughts
Running llama.cpp on IBM i is not only possible—it’s fun and incredibly rewarding! With just a few tweaks, you can bring cutting-edge LLM tech to your favorite midrange system Here’s a quick recap of what we covered:
Setup & Build
- Installed necessary open source packages
- Patched the
RLIMIT_MEMLOCKlogic - Configured and built
llama.cppfrom source on Power9/Power10
Model Preparation
- Downloaded IBM i–compatible model locally
- Transferred to IBM i manually for use with
llama.cpp
Running Llama.cpp
- Used the CLI (
llama-cli) for quick tests and prompts - Launched
llama-runfor interactive chat - Hosted the built-in HTTP server with
llama-server - Sent test requests via
curland explored the Web UI in a browser
Highlights
- Built natively for IBM i
- Works with
ggufmodels likeLlama-3.2-1B-Instruct - Fully local, zero dependencies, minimal configuration
- Supports HTTP API and interactive usage modes
Stay tuned for a follow-up post with performance tips, token benchmarks, and real-world IBM i use cases!